Confluent Cloud Incident Automation with GenAI
How NeuBird automates Confluent Cloud incident automation, from consumer lag to authorization errors, cutting MTTR with human-approved fixes. Start today.
A joint post from the teams at NeuBird and Confluent Confluent Cloud incident automation lets application teams resolve Kafka client issues, from unexpected consumer lag to authorization errors and connectivity problems, without manually piecing together logs, metrics, and dashboards. For organizations running managed Confluent, the company behind Apache Kafka® as a central nervous system for their data, ensuring smooth operations is mission-critical. While Confluent Cloud eliminates much of the operational burden of managing Kafka clusters, application teams still need to monitor and troubleshoot client applications connecting to these clusters. Traditionally, when issues arise, engineers must manually piece together information from multiple observability tools, logs, and metrics to identify root causes. This process is time-consuming, requires specialized expertise, and often extends resolution times. Today, we're excited to share how NeuBird, running its GenAI-powered Production Ops Agent, is transforming this experience by automating the investigation and resolution of Confluent Cloud incidents, with every fix held behind human approval and a full audit trail.
The Foundation: Kafka Client Observability with Confluent
Confluent's observability setup provides a strong foundation for monitoring Kafka clients connected to Confluent Cloud. It leverages:
- A time-series database (Prometheus) for metrics collection
- Client metrics from Java consumers and producers
- Visualization through Grafana dashboards
- Failure scenarios to learn from and troubleshoot
The demo is incredibly valuable for understanding how to monitor Kafka clients and diagnose common issues, but it still relies on human expertise to interpret the data and determine root causes.
Enhancing the Experience with Kubernetes and AI-driven Automated Incident Response
NeuBird builds on Confluent's robust observability foundation by integrating our GenAI-powered Production Ops Agent directly into the Kafka monitoring ecosystem. This combination goes beyond monitoring to introduce intelligent Confluent Cloud incident automation, significantly reducing Mean Time to Resolution (MTTR). Here's how NeuBird augments Confluent's observability with three significant improvements:
- Kubernetes Deployment: We've containerized the entire setup and made it deployable on Kubernetes (EKS), making it more representative of production environments and easier to deploy.
- Alert Manager Integration: We've added Prometheus Alert Manager rules that trigger PagerDuty incidents, creating a complete alerting pipeline.
- Audit Logging: We've expanded the telemetry scope to include both metrics and logs in CloudWatch, giving a more comprehensive view of the environment.
Most importantly, we've integrated NeuBird's Production Ops Agent to automatically investigate and resolve incidents as they occur, significantly reducing Mean Time to Resolution (MTTR).
Seeing it in Action: Authorization Revocation Scenario
Let's walk through a real-world scenario from the Confluent demo: the "Authorization Revoked" case, where a producer's permission to write to a topic is unexpectedly revoked.
The Traditional Troubleshooting Workflow
In the original demo workflow, here's what typically happens:
- An engineer receives an alert about producer errors
- They log into Grafana to check producer metrics
- They notice the Record error rate has increased
- They check Confluent Cloud metrics and see inbound traffic but no new retained bytes
- They examine producer logs and find TopicAuthorizationException errors
- They investigate ACLs and find the producer's permissions were revoked
- They restore the correct ACLs to resolve the issue
This manual process might take 15-30 minutes for an experienced Kafka engineer, assuming they're immediately available when the alert triggers.
The NeuBird-Automated Workflow
With our enhanced setup including NeuBird, the workflow is transformed:
- Prometheus Alert Manager detects increased error rates and triggers a PagerDuty incident
- NeuBird automatically begins investigating the issue by:
- Retrieving and analyzing producer metrics from Prometheus
- Correlating with Confluent Cloud metrics
- Examining producer logs for error patterns
- Checking AWS CloudWatch for audit logs showing ACL changes
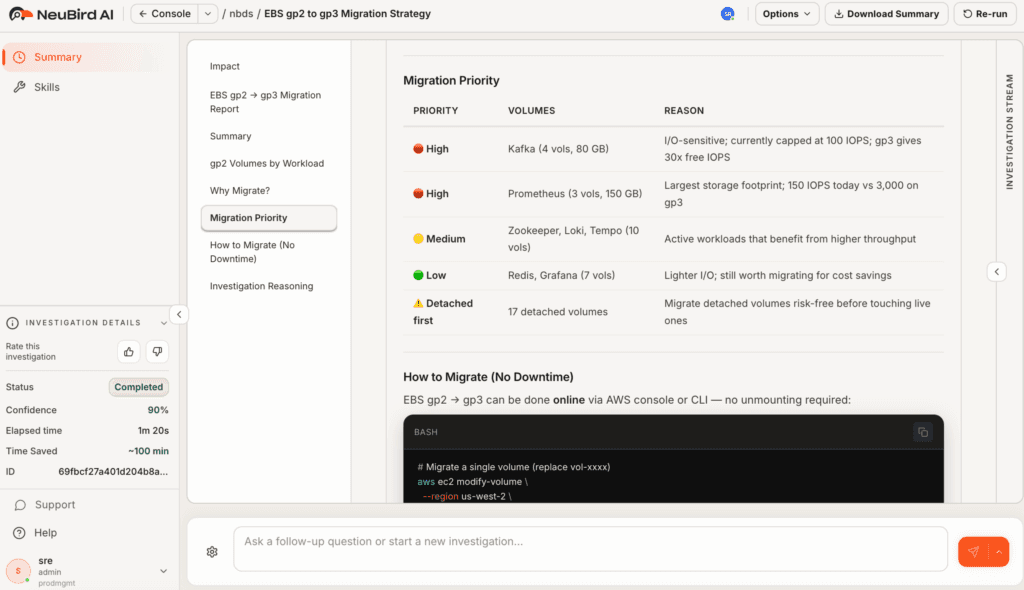
- Within minutes, NeuBird identifies the TopicAuthorizationException and links it to recent ACL changes
- NeuBird generates a detailed root cause analysis with specific remediation steps
- An engineer reviews NeuBird's findings and applies the recommended fix, or approves NeuBird to implement the fix under a policy gate with a full audit trail
The entire process is reduced to minutes, even when the issue occurs outside business hours. Every action stays behind human approval, backed by a full audit trail, so your specialized Kafka engineers spend their time on strategic work rather than routine troubleshooting.
SRE Automation with AI: How the Production Ops Agent Fits
Confluent Cloud incident automation is one workload in a broader shift toward SRE automation with AI. The point of SRE automation with AI is not to remove engineers from the loop; it is to remove the manual correlation work that sits between an alert firing and a root cause being understood. NeuBird's Production Ops Agent runs on the Agentic Operations Center, one governed platform that accesses your telemetry and your LLMs in place, remembers every investigation, and gates execution behind policy with human approval on every action.
For a Confluent Cloud team, that means:
- Access: the agent reads your Prometheus metrics, Confluent Cloud metrics, producer and consumer logs, and CloudWatch audit logs where they already live, without you shipping copies of that telemetry into a new store.
- Remember: each investigation leaves a durable memory of the conclusion, the causal chain, the evidence it cited, and who approved the fix, with zero telemetry storage. The memory holds conclusions and approvals, never a copy of your logs, metrics, or traces. The next TopicAuthorizationException does not start from a blank page.
- Serve: findings arrive in Slack, PagerDuty, and Jira where your on-call already works, and your own agents can connect over MCP as further tenants.
Across Prevent, Resolve, and Operate, the agent detects the weak signals that precede a Kafka incident, correlates 15+ sources in parallel to produce RCA in under 5 minutes, and hands a reviewed recommendation to a human. Every action is 100% human-approved under a policy gate that logs an audit trail. That is what SRE automation with AI looks like when it is scoped to a governed platform rather than a black box.
Demo Video
In this video, we demonstrate the complete workflow:
- How we deploy the enhanced Confluent observability solution to Kubernetes
- Triggering the authorization revocation scenario
- Watching NeuBird's Production Ops Agent automatically detect, investigate, and diagnose the issue
- Reviewing NeuBird's detailed analysis and remediation recommendations
- Implementing the fix and verifying the resolution
The Technical Architecture
Our enhanced solution builds upon Confluent's observability foundation with several key components:
- Kubernetes Deployment: All components are packaged as containers and deployed to EKS using Helm charts, making the setup reproducible and scalable.
- Prometheus and Alert Manager: We've added custom alerting rules specifically designed for Confluent Cloud metrics and common failure patterns.
- AWS CloudWatch Integration: Both metrics and logs are forwarded to CloudWatch, providing a centralized location for all telemetry data.
- NeuBird Integration: NeuBird connects securely to your telemetry sources, leveraging GenAI to understand patterns, correlate events, and recommend precise solutions.
The architecture respects all security best practices: NeuBird never stores your telemetry data (zero telemetry storage), operates with minimal permissions, and all analysis happens in ephemeral, isolated environments.
Real-World Impact
Organizations using NeuBird with Confluent Cloud have seen significant operational improvements:
- Reduced MTTR: Issues that previously took hours to diagnose are now resolved in minutes
- Decreased Alert Fatigue: Engineers are only engaged when human intervention is truly needed
- Knowledge Democratization: Teams less familiar with Kafka can confidently operate complex Confluent Cloud environments
- Improved SLAs: With faster resolution times, application availability and performance metrics improve
As one example, an enterprise IT storage company reduced their MTTR for DevOps pipeline failures by implementing NeuBird. When experiencing a crash loop with one of their applications causing production downtime, NeuBird automatically picked up the alert from PagerDuty, investigated the issue, and determined that the crashes were happening due to a recent application deployment. NeuBird recommended which specific application and process needed to be rolled back, dramatically reducing resolution time.
Frequently Asked Questions
What is Confluent Cloud incident automation?
Confluent Cloud incident automation is the practice of using an AI-driven Production Ops Agent to detect, investigate, and diagnose Kafka client incidents, such as consumer lag, TopicAuthorizationException errors, and connectivity failures, without an engineer manually correlating Prometheus metrics, Confluent Cloud metrics, and CloudWatch logs by hand. NeuBird produces a root cause analysis with remediation steps in minutes and keeps every fix behind human approval.
How does SRE automation with AI keep engineers in control?
SRE automation with AI, as NeuBird practices it, runs investigation autonomously but gates execution. The Production Ops Agent recommends a fix and can apply it, but only under a policy that requires human approval, and every action lands in a full audit trail. The agent removes the manual correlation work, not the decision: an engineer signs off before anything changes in production.
Does NeuBird store my Confluent Cloud telemetry?
No. NeuBird operates with zero telemetry storage. It accesses your Prometheus, Confluent Cloud, and CloudWatch data in place and its memory holds only the conclusions, causal chains, evidence citations, and approvals from each investigation, never a copy of your logs, metrics, or traces.
Getting Started
Want to try this enhanced observability setup with your own Confluent Cloud environment? Here's how to get started:
- Start with the original Confluent observability demo to understand the components
- Check out our GitHub repository for the Kubernetes-ready version with Prometheus Alert Manager rules
- Schedule a demo to see NeuBird in action with your Confluent Cloud environment
Conclusion
The combination of Confluent Cloud and NeuBird represents a powerful shift in how organizations operate Kafka environments. By leveraging Confluent's rich telemetry data and NeuBird's GenAI-powered Confluent Cloud incident automation, teams can significantly reduce operational overhead, improve reliability, and focus on delivering value rather than troubleshooting infrastructure. As data streaming becomes increasingly central to modern applications and with availability of fully managed Kafka and Flink solutions in Confluent Cloud, this type of intelligent automation will be essential for scaling operations teams effectively, letting them support larger, more complex deployments without sacrificing reliability. We're excited to continue innovating at the intersection of observability, AI, and data streaming. Let us know in the comments how you're approaching observability for your Confluent Cloud environments!